Give your team an AI co-worker that can act.
From an employee question to a reviewed workflow: build, run and improve agents on your open-source models, through chat, CLI or MCP/API.
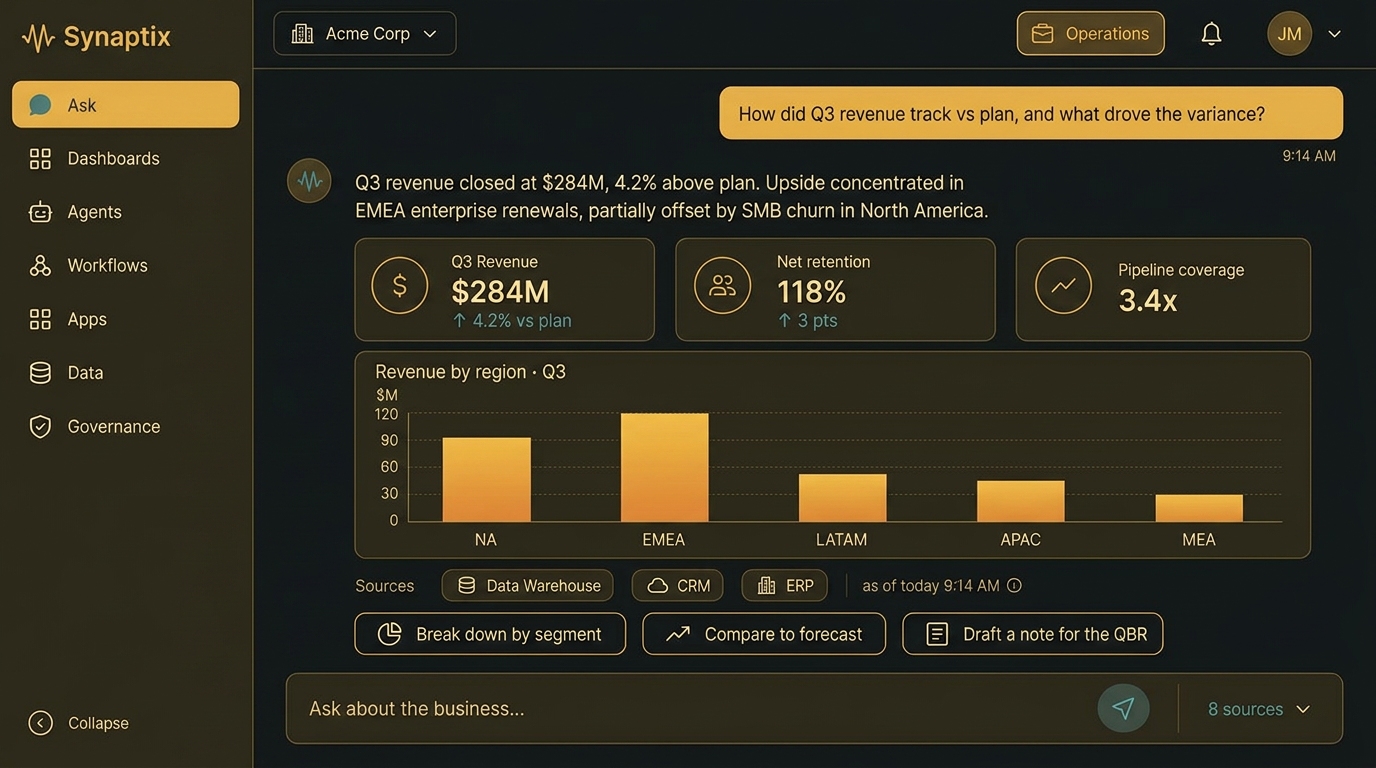
One shell — adapts to your tenant, data and brand.
A useful answer is only the beginning.
Enterprise work crosses documents, systems and people. Give an agent the tools to collect context, prepare a decision and ask for approval before it acts.
Explore example workflowsOne agent. Three surfaces.
Same identity, memory, tools and policy — whether a VP is chatting, an engineer is scripting, or another agent is calling in over MCP.
For every employee
Claude-style co-worker in the browser and desktop. Ask, approve, review dashboards, kick off workflows.
For developers
`synaptix` in your terminal, scripts and CI. Run agents locally, pipe outputs, ship reproducible tasks.
For agents & apps
Expose every agent as an MCP server and REST/streaming API. Callable from Cursor, Claude, Codex and your own apps.
One identity plane. One policy engine. One audit trail across every surface.
One super-agent. Eight ways to use it.
Ask, Dashboards, Agents, Workflows, Apps, Data and Governance — in front of every team and every system.
Chat & Ask
Grounded answers over your data — with citations and next actions.
Code
A coding co-worker that reads your repos, writes PRs and ships tickets.
Workflows
Visual builder for multi-step, multi-agent workflows with human gates.
Agents
Scheduled, on-event and on-demand — briefings, notifiers and drafters.
Apps
Package workflows as internal apps — no prompt required.
Dashboards
Agent-generated dashboards with live sources and freshness stamps.
Data
Governed connectors to Snowflake, Databricks, SAP, Salesforce and 200+ systems.
Governance
Policy packs, PII/PHI minimization, approvals, audit and evals — built in.
Your models. Your weights. No frontier lock-in.
Every capability runs on the open models you choose — Llama, Qwen, Mistral, DeepSeek, GPT-OSS or your fine-tunes — served on the Inference Platform at frontier latency. Closed models stay optional via the AI Gateway.
Improve agents against the tasks they actually do.
Trace each run, evaluate its result, and compare proposed changes before promoting them. Task-specific evaluators help teams weigh accuracy alongside cost.
Capture every run
Prompts, tool calls, tokens, latency, cost and outcome — logged per step, linked to the request, the user and the policy in effect.
Task-specific evaluators
LLM-judge, rules, golden sets and human review. Each task type gets its own rubric; every run gets a score.
Tune what wins
Prompt, router, tool-choice, model and RL updates are proposed continuously — promoted only when evals beat the incumbent on quality and $/run.
Versioned & reversible
Every agent version is diffed, signed, budget-capped and one-click revertible. Auditors see who changed what, when, and why it shipped.
Right model. Right tool. Right budget. Per step.
Set budgets for each workflow and choose models by the quality a task needs. Escalate difficult steps when evaluations call for it; avoid paying for a larger model on every step.
Ask, build, deploy, run.
Business users ask. IT composes. The harness runs, scores and improves every deployed agent — humans in the loop where it matters.
Business users ask. The co-worker answers.
Plain-language questions get grounded answers with KPIs, charts, sources and next actions.
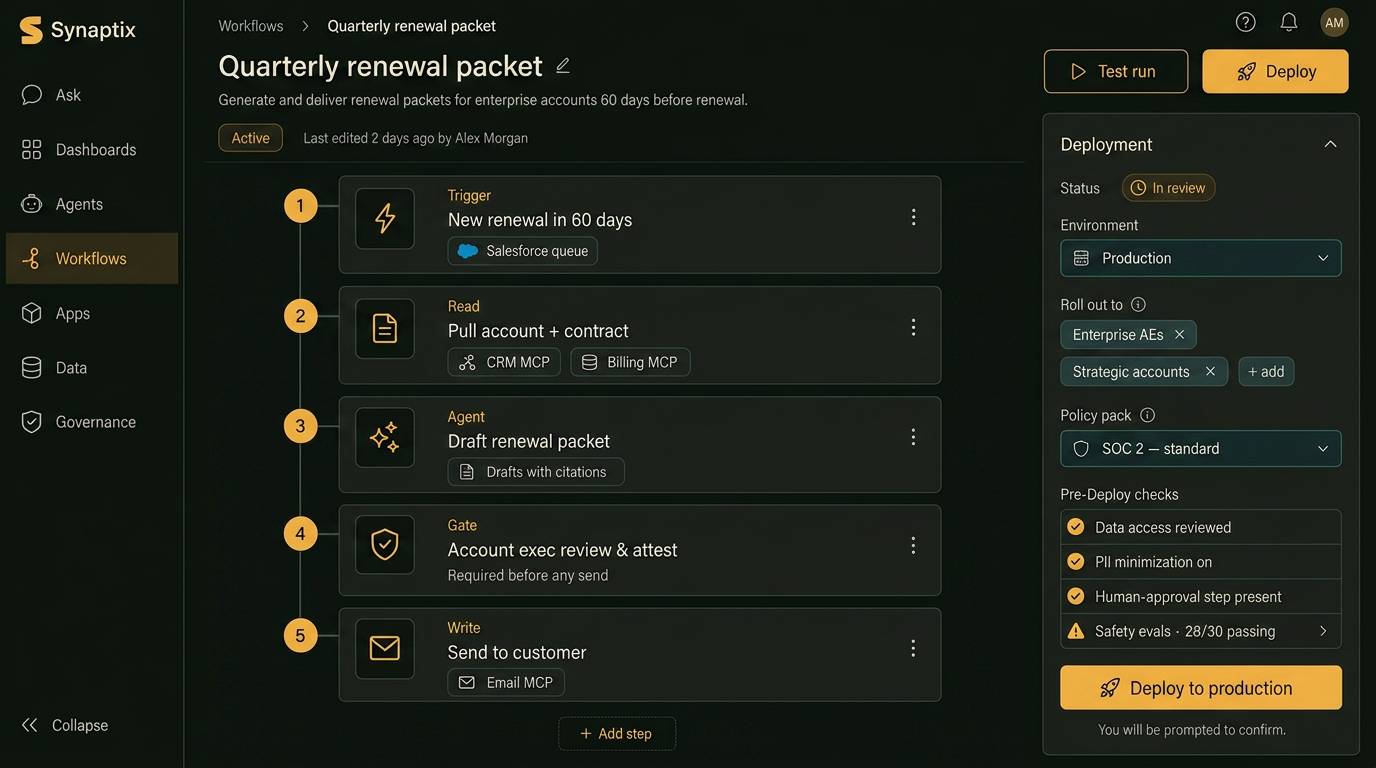
IT and ops compose the workflow.
Wire triggers, reads, agents, gates and writes.
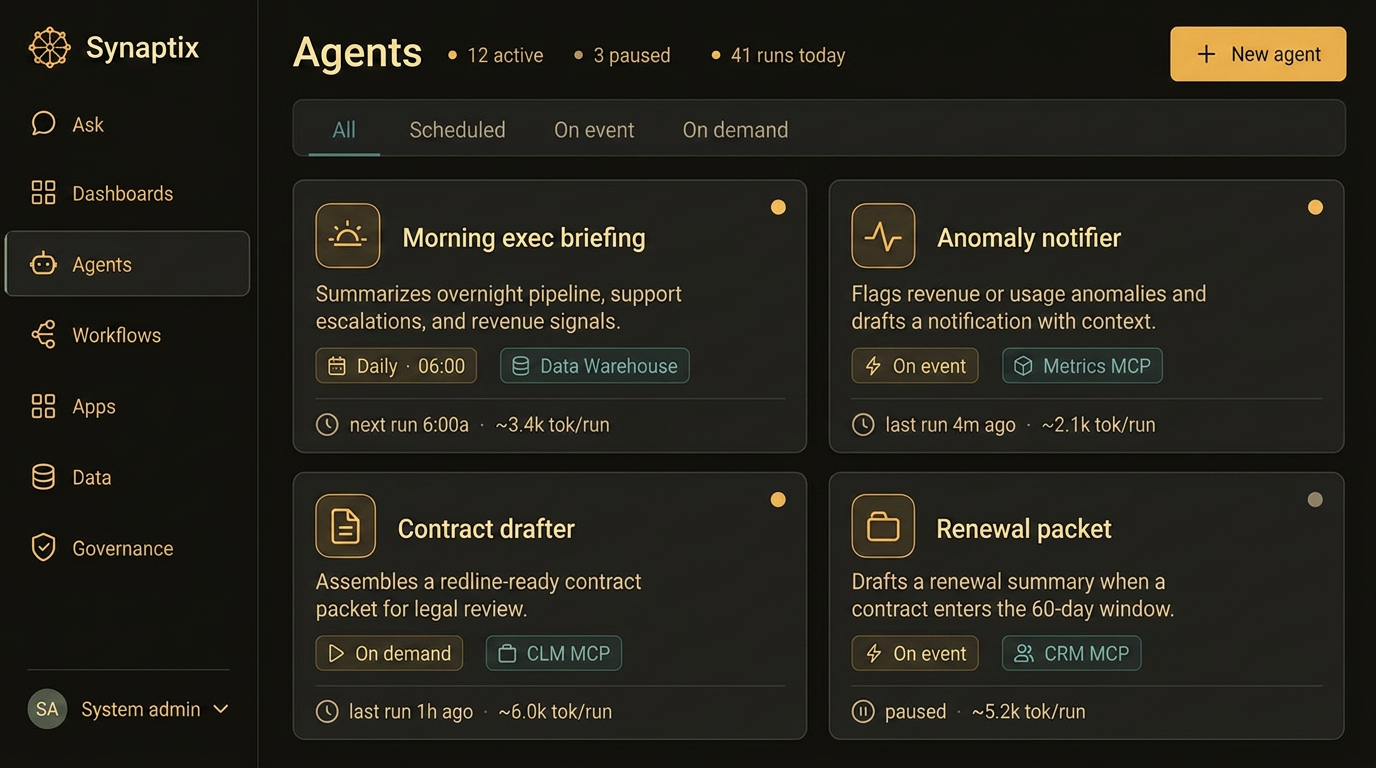
Agents run on schedule, on event, on demand.
Every run observable.
Same product. Your data, policies, brand.
Connectors, policy packs, agent library and workflows adapt to your industry on day one.
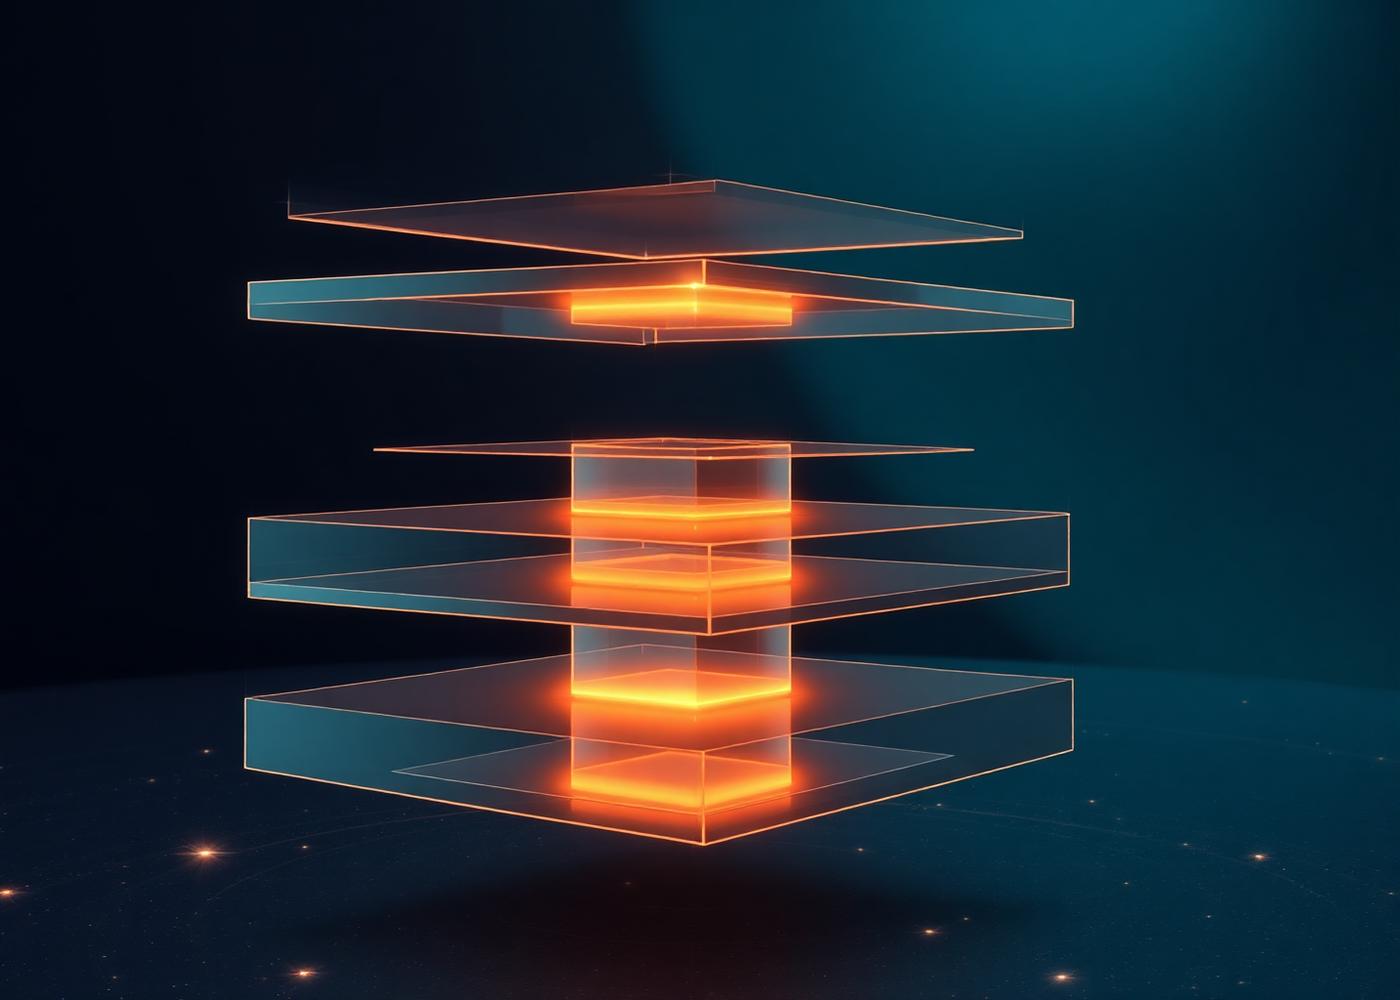
Six layers. One control plane.
Silicon to supervisor — one API, one console. Each layer best-in-class; together they compound.
Go deeper on the Agent Platform
Six layers, one control plane
The full architecture deep-dive — silicon to supervisor.
Agent Platform — product brief
Six layers, deployment options and operations in one PDF.
The Agent OS: not a framework
Why agentic AI needs an operating system.
Self-improving agents in production
Continuous evals, RL loops and the optimization moat.
Ready to operationalize your agents?
Talk to our team about a pilot on Synaptix Cloud or on-prem.